Published February 4, 2026 in AI Video · Updated September 9, 2026
Video to Text Converter: Auto Transcription Tools

Founder & Content Creator at Vibrantsnap · 10 min read
Every video we publish at Vibrantsnap gets converted to text before it ships. Not because transcripts are glamorous — because a video to text converter turns one recording into captions, a blog draft, documentation, and a searchable archive entry, automatically, in about the time it takes to make coffee. The same job used to cost 4–6 hours of manual typing per hour of footage. Now it's a transcription pass and a review.
This guide is the workflow I actually use: which tools convert video (and plain audio) to text reliably, what determines whether you get 95% accuracy or a mess, which export format to pick, and three concrete ways to put the transcript to work. I build a screen recorder with AI captions, so I have skin in this game — I'll flag where my product fits and where a different tool is honestly the better call.
How automatic transcription actually works
Understanding the pipeline takes two minutes and saves you from blaming the wrong thing when a transcript comes back rough. Every AI transcription tool runs roughly the same four stages:
- Audio processing — the engine extracts and normalizes the audio track. This is worth internalizing: the video part of your file is irrelevant. Only the audio is transcribed.
- Acoustic modeling — sounds are mapped to phonemes, the raw building blocks of speech.
- Language modeling — the model predicts the most likely word sequence from those phonemes. This is why transcripts read fluently and also why they confidently write "vibrant snap" instead of your product name: the model picks probable words, not your words.
- Formatting — punctuation, capitalization, speaker labels, and timestamps get layered on.
The practical consequence: accuracy is decided mostly at stage one, by the audio you feed in, and the errors that survive are concentrated in proper nouns and jargon that the language model has no reason to expect. Both of those facts shape the workflow later in this post.
The best video to text converters in 2026
| Tool | What it is | Output formats | Price | Best for |
|---|---|---|---|---|
| Vibrantsnap | Screen recorder with AI captions | Editable captions, burned-in subtitles | Free to record; Pro from $49/mo | Demos and tutorials you're about to record |
| Descript | Transcript-based video editor | SRT, VTT, text, Word | Free (1 hr); from $12/mo | Editing existing video by editing text |
| Otter.ai | Meeting transcription service | Text, SRT | Free (300 min/mo); Pro ~$8.33/mo | Meetings, interviews, lectures |
| Rev | AI + human transcription service | SRT, VTT, text, Word | AI $0.25/min; human $1.50/min | Legal, medical, high-stakes accuracy |
| OpenAI Whisper | Open-source transcription model | Text, SRT, VTT, JSON | Free (self-hosted) | Developers, privacy, bulk processing |
| VEED.io / Kapwing | Browser editors with captioning | SRT, VTT, burned-in | Free tiers; paid plans | Styled captions for social clips |
| YouTube | Auto-captions on any upload | SRT, text | Free | Zero-budget transcription |
TL;DR: if the video already exists, Descript or an upload service. If the video doesn't exist yet, record it with a tool that transcribes as you go and skip the upload step entirely. If accuracy failures have legal consequences, pay a human at Rev. If you have a terminal and patience, Whisper is free.
Vibrantsnap — the transcript as a byproduct of recording
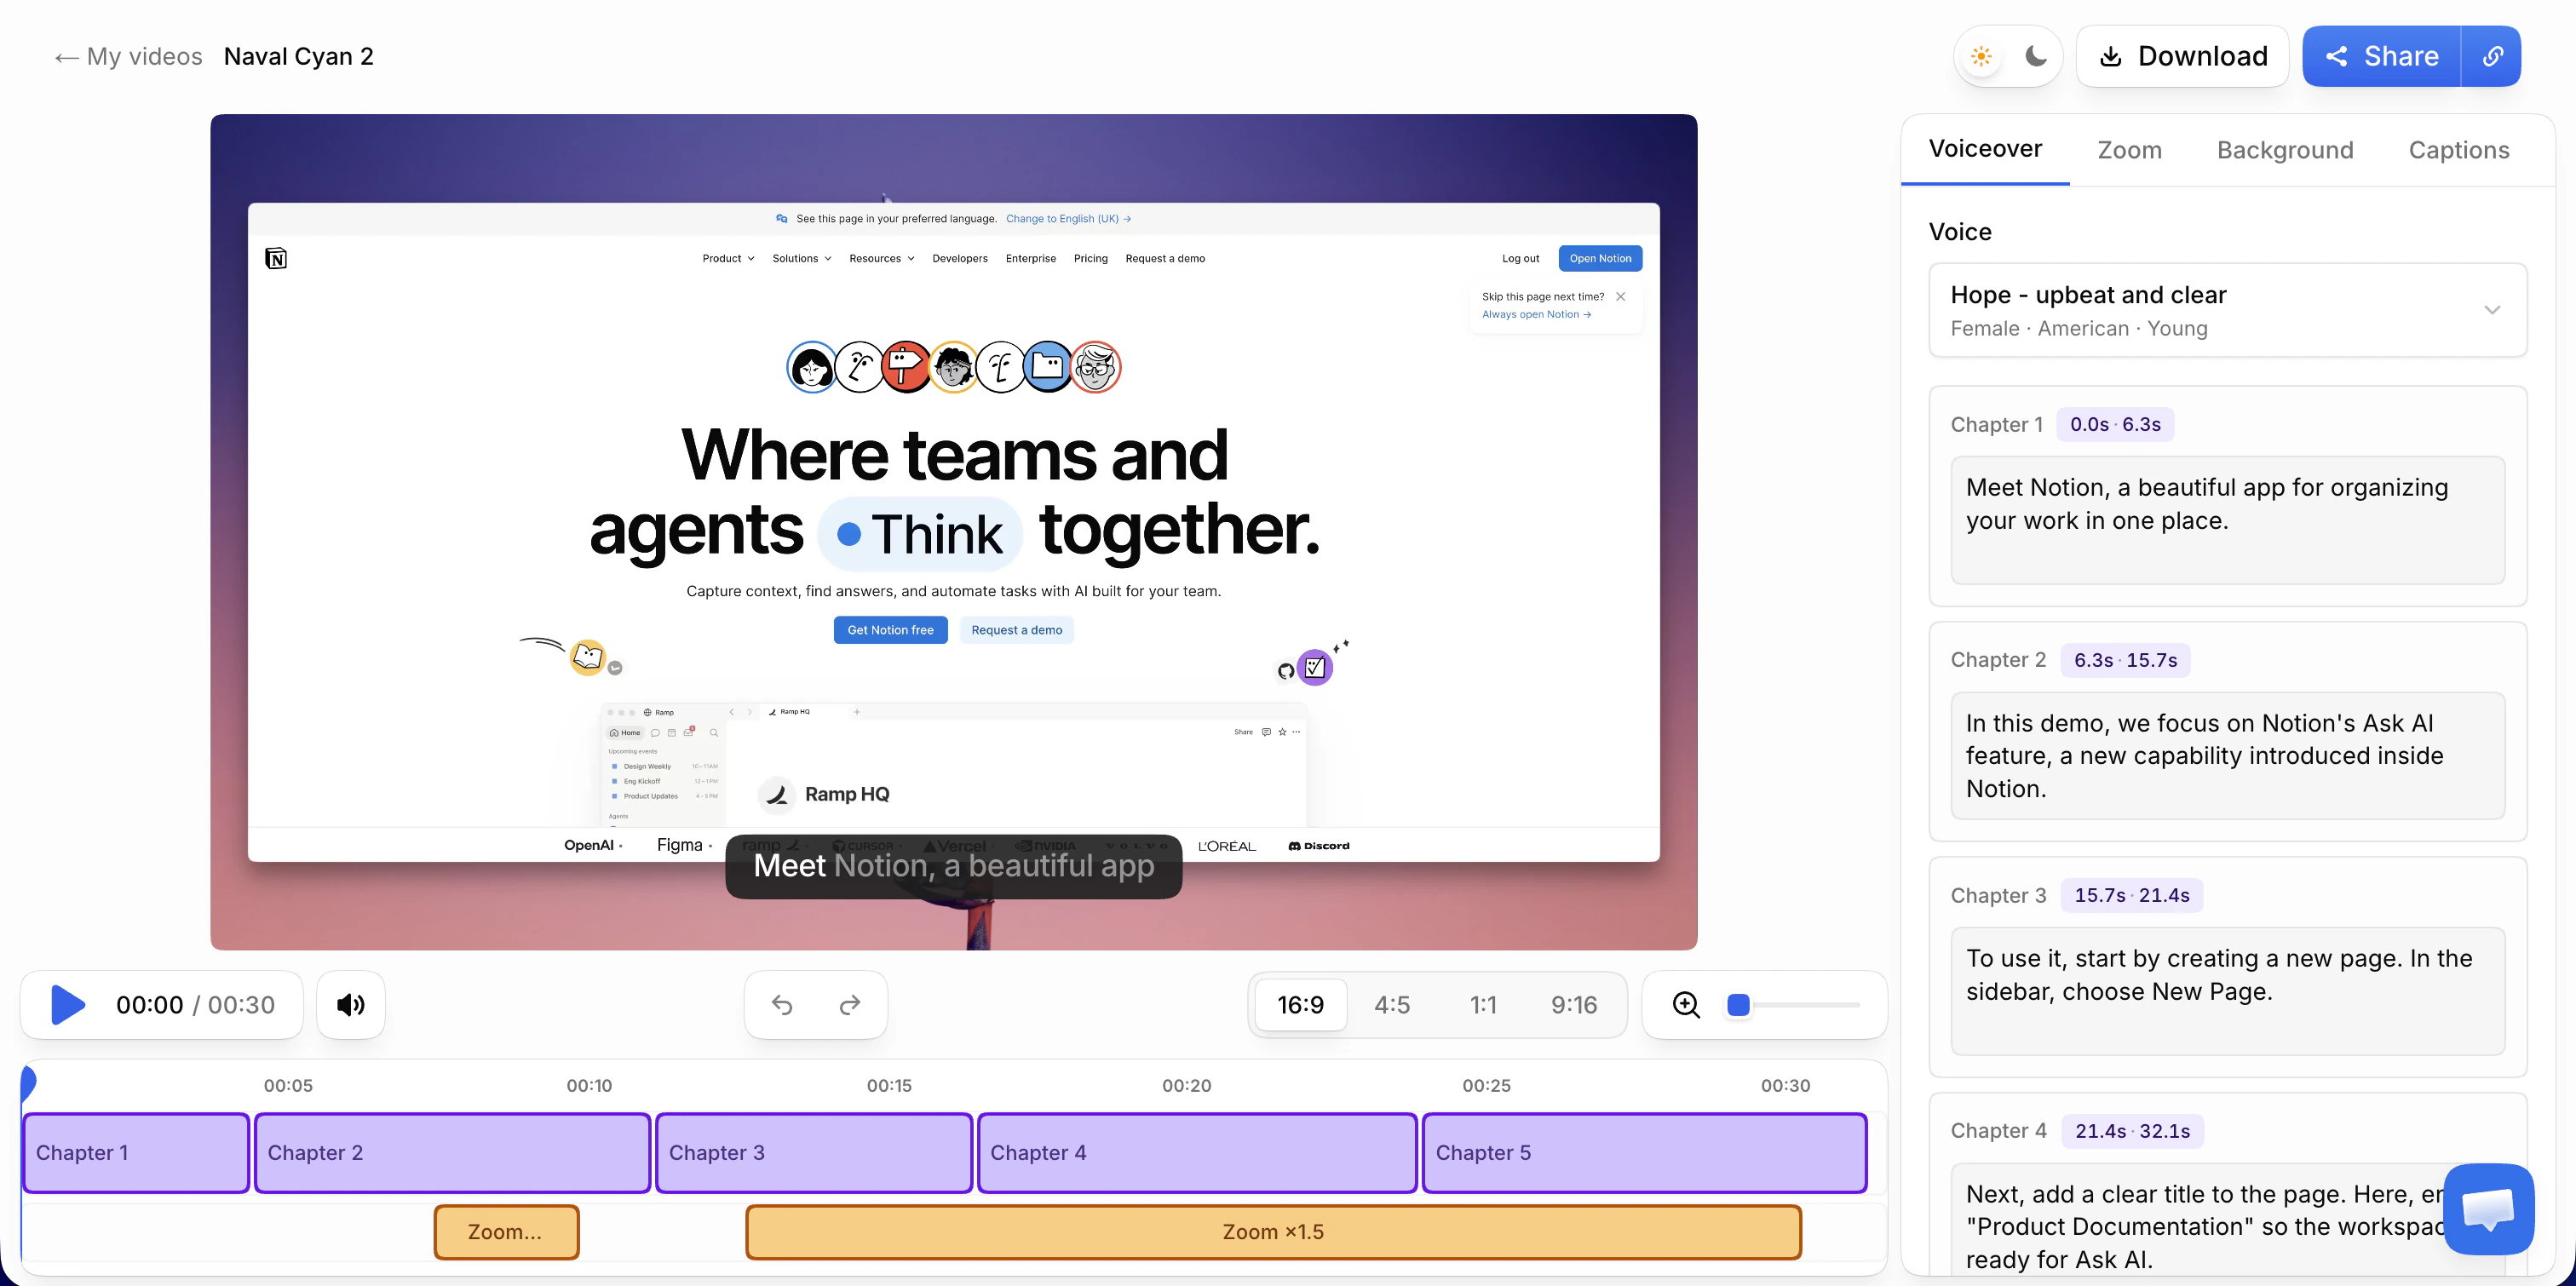
Most people shopping for a video to text converter are converting videos they recorded themselves — demos, tutorials, walkthroughs. That's the case where converting after the fact is the long way round. When you record with Vibrantsnap, the AI captions generate an editable, word-by-word transcript of your narration automatically, on every plan including free. Fix a misheard product name once and the caption and transcript both update; export the result as subtitled video, with the transcript doing double duty as your documentation draft.
It sits inside the same AI video editor workflow that removes silences and filler words and auto-zooms on your clicks — so the transcript you get matches the edited video, not the rambling first take. Free covers recording, editing, and preview; watermark-free exports start at $49/month on Pro — full plan breakdown here.
Honest limit: Vibrantsnap transcribes what it records. If you have an existing two-hour interview file sitting on a drive, the upload tools below are the right shape for that job.
Descript — edit the video by editing the transcript
Descript's whole premise is that the transcript is the editing interface. Import a file, get a transcript in minutes, delete a sentence from the text and it disappears from the video. Word-level timestamps, speaker labels, find-and-replace across a whole project. Free tier includes one hour of transcription; paid starts around $12/month. If your workflow is "transcribe, then cut," nothing else feels as direct.
Otter.ai — built for meetings
Otter transcribes in real time, joins your Zoom/Teams/Meet calls, identifies speakers, and files everything into a searchable library. The free tier's 300 minutes per month covers a normal meeting load. It accepts video uploads too, but its DNA is conversation: for a polished tutorial you'll fight its formatting more than with Descript.
Rev — when 95% isn't good enough
Rev sells both AI transcription ($0.25/minute, ~90%+ accuracy) and human transcription ($1.50/minute with a 99% accuracy guarantee, typically 12+ hours turnaround). The human tier is the answer for legal depositions, medical content, and anything where a wrong word costs more than $1.50/minute. For everything else, the AI tier competes with the tools above without beating them.
OpenAI Whisper — free, private, technical
Whisper is the open-source model many commercial tools run under the hood. Self-hosting it costs nothing, keeps sensitive audio on your own hardware, and handles dozens of languages — but there's no interface, processing speed depends on your machine, and you're the support team. Ideal for developers and bulk archives; wrong for anyone who just wants a button.
YouTube — the free default
Upload a video (unlisted is fine), wait a few hours, download the auto-captions as SRT or a plain transcript. Accuracy hovers around 90% on clear speech — enough for a searchable archive, rough for publication without cleanup. It's the zero-budget option, and it's genuinely fine as one.
Audio to text: the same job without the picture
Here's the thing the category names hide: an audio to text converter and a video to text converter are the same tool. Transcription engines only ever process the audio track — the pixels never enter into it. So everything above applies directly to podcasts, voice memos, phone interviews, and meeting recordings.
A few audio-specific notes from doing this weekly:
- File formats: every serious tool accepts MP3, WAV, and M4A alongside MP4 and MOV. WAV gives the engine the cleanest signal; a well-encoded MP3 transcribes indistinguishably in practice.
- Big files: if a tool's upload limit chokes on a 2 GB video, extract the audio track first — you'll upload a 60 MB file and get the identical transcript.
- Best tool by audio source: Otter for meetings (speaker identification is the killer feature when four people talk), Whisper for private or bulk material, Rev human for anything with legal weight, Descript when the audio is a podcast you'll also edit.
- Speaker labels matter more than accuracy for multi-voice audio. A 96%-accurate transcript where you can't tell who said what is less useful than a 93% one with clean diarization. Check that feature before you check the accuracy claims.
What actually determines accuracy
Vendors all claim "95%+ accuracy," and on their demo audio they're telling the truth. Whether you get that number depends on factors that are mostly under your control before you hit record:
Helps accuracy: a decent microphone close to the speaker, a quiet room, one voice at a time, a steady pace, and common vocabulary.
Hurts accuracy: laptop mics from across the room, background music, overlapping speakers, heavy accents the model wasn't trained on, and dense jargon.
You can't fix accents and you shouldn't dumb down vocabulary — but mic distance and background noise are five-minute fixes that move the accuracy number more than switching tools ever will. I've seen the same recording setup go from "every third product name is wrong" to near-perfect by moving a microphone 40 centimeters closer.
Then there's the review pass, which no AI transcript should skip. Mine takes five minutes per ten minutes of footage:
- Listen while reading at 1.5x — errors jump out when your ears and eyes disagree.
- Fix proper nouns first — names, brands, product terms. This is where 80% of the errors live.
- Catch homophones — their/there, "weight" for "wait." Grammatically fine, factually wrong, invisible to spellcheck.
- Check punctuation at sentence boundaries — misplaced periods quietly change meaning.
- Confirm speaker labels on multi-voice recordings.
Transcript formats: which export to pick
| Format | What it carries | Use it for |
|---|---|---|
| SRT | Numbered entries + timestamps | Captions — accepted by every platform and editor |
| VTT | Timestamps + styling options | HTML5 web players, embedded video |
| Plain text | Words only, no timing | Blog drafts, documentation, searchable archives |
| Word/Doc | Formatted document | Meeting minutes, transcripts you send to clients |
| JSON | Word-level timestamps + confidence scores | Developers, automation, clip-search tools |
The only real mistake here is exporting plain text when you'll later want captions — the timing information doesn't come back without re-running the transcription. When in doubt, export SRT; stripping timestamps out of an SRT takes seconds, adding them back takes a re-upload.
Three workflows I run every week
Abstract benefits are easy to list. Here's what converting video to text looks like in practice, with real inputs and outputs.
1. Transcribe a product demo into editable captions
Every feature demo we ship gets captions, because most prospects watch muted in a feed or an email client. The workflow: record the demo in a browser tab, let the AI cut the dead air — trimming silence before captioning matters, because dead air produces caption gaps that look broken; our silence-removal guide covers that step — then review the generated transcript, fix the two or three product terms it misheard, and export with captions burned in. Ten minutes end to end. If you're doing this with separate tools, our walkthrough on adding captions to video automatically maps the same flow across other stacks.
2. Subtitle a social clip
Short vertical clips live or die on captions — the platforms report 80%+ of feed video plays start muted. Take the SRT from your transcription tool, restyle it for the platform (bigger type, high contrast, two lines max), and either burn it in or upload it as a caption file. For clips under a minute, the review pass is two minutes; skipping it is how "our product's cash flow feature" becomes "our product's cash cow feature" in front of ten thousand people. Ask me how I know.
3. Repurpose a webinar into a doc and a blog post
This is the highest-leverage one. A 40-minute webinar transcript is 6,000 words of raw material: cut the greetings and the Q&A dead ends, restructure the remaining sections under headings, tighten the spoken grammar, and you have a solid documentation page or blog draft in an hour — versus half a day writing from memory. One recording becomes four assets: the video, the captions, the doc, and a thread of quotable lines. The full playbook is in our guide to turning one video into many pieces of content.
How to choose in 30 seconds
- The video doesn't exist yet → record with built-in transcription (Vibrantsnap) and skip the convert step.
- Existing file, and you'll edit it → Descript.
- Meetings and interviews → Otter.ai.
- Errors have legal or medical consequences → Rev human transcription.
- Hundreds of files, or privacy constraints → Whisper, self-hosted.
- No budget at all → YouTube auto-captions, plus a careful review pass.
The tools have converged enough that workflow fit beats accuracy benchmarks. Pick the one that removes a step from what you already do — for me, that's the one where the transcript exists before I've finished recording.
Frequently asked questions
What is the best video to text converter? It depends on where your video starts. If you still need to record it, Vibrantsnap generates an editable word-by-word transcript as AI captions while you record your screen. For editing an existing file through its transcript, Descript is the strongest option. For meetings, Otter.ai transcribes in real time. For legal or medical content where errors are expensive, Rev's human transcription guarantees 99% accuracy. For developers and bulk jobs, OpenAI Whisper is free to self-host.
How do I convert video to text for free? Three reliable free routes: upload the video to YouTube (it can stay unlisted) and download the auto-generated captions or transcript; run OpenAI Whisper locally if you are comfortable with a command line; or use the free tiers of Descript (one hour of transcription) and Otter.ai (300 minutes per month). Free options usually mean slower processing or manual cleanup, but the transcripts are perfectly usable after a review pass.
How accurate is automatic video transcription? On clean audio — a decent microphone, one speaker, no background noise — modern tools consistently hit 95% accuracy or better. Accuracy drops with overlapping speakers, heavy accents, fast speech, and technical vocabulary. The predictable failure points are proper nouns, product names, and homophones, which is why every AI transcript needs one review pass while listening to the audio. Human transcription services like Rev still lead at 99% for difficult audio.
Can I convert audio files to text with the same tools? Yes. Transcription engines only ever process the audio track, so every video-to-text tool handles MP3, WAV, or M4A files just as well as MP4. Podcasts, voice memos, and meeting recordings go through the identical workflow. If a tool has upload size limits, extracting the audio track from a large video before uploading gets you the same transcript from a much smaller file.
What format should I export a transcript in? Match the format to the destination. SRT is the universal choice for captions — every video platform and editor accepts it. VTT is the same idea optimized for web players. Plain text is best for blog drafts, documentation, and anything you want searchable. Word exports suit meeting minutes you need to share, and JSON carries word-level timestamps for developers building automation on top of transcripts.
Comparison